Your Internal Developer Platform Will Not Survive AI Unchanged
AI changes the job of an internal developer platform. Model access, data context, evaluation, agent runtime, cost attribution and policy now need a supported path, not six teams inventing six different stacks.
Audio edition
Read by a synthetic voice cloned from John with his consent. About the audio edition
Your internal developer platform can deploy an agent successfully and still leave you unable to explain what it did. Containers are healthy, the release passed CI, and the endpoint responds. None of that tells you which documents the agent retrieved, which tools it called, or why one request cost ten times another.
I would extend the existing platform to answer those questions. Identity, deployment, incident response and cost allocation already have owners there. AI adds controls those owners must support. Creating another platform does not remove the need to join them up.
That recommendation has a condition. Your platform must already offer services teams choose to use, with support and capacity to change them. If it is a ticket queue around Kubernetes, adding an AI catalogue will not turn it into a product.
Follow one failed request
Consider a hypothetical customer-support agent. It retrieves account information and policy documents, drafts a response, and can request a refund through a tool. The application team deploys it through the usual pipeline.
A customer receives an incorrect answer. Around the same time, the team’s model bill rises. Support needs to know what happened; finance needs to know whether the extra spend bought useful work.
An application trace shows a successful HTTP request. The provider invoice shows token consumption. Neither identifies the policy document used in that answer or whether the agent retried the refund tool. The deployment record identifies the container image, but the prompt was edited separately and the model was selected through a provider alias.
The investigation crosses four boundaries: application release, model dependency, retrieved data and tool execution. Someone must connect them. A platform that records only the first leaves the application team to assemble the rest during an incident.
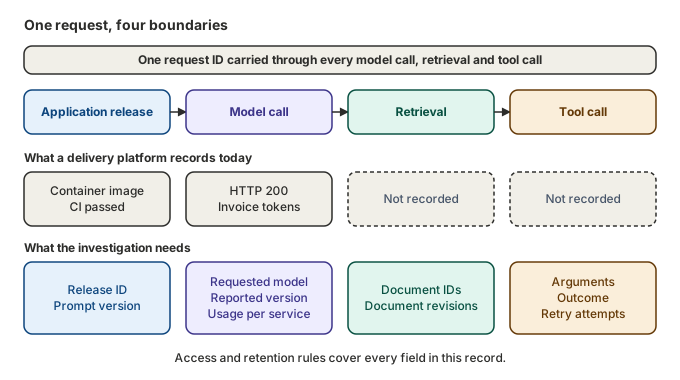
Start with a request identifier carried through every model call, retrieval and tool invocation. Record the application release, prompt version, requested model and provider-reported version where available, retrieved document identifiers and revisions, tool arguments and outcomes, and usage attributed to the owning service. Set access and retention rules for that record: debugging does not justify putting customer data in an unrestricted log.
That gives you evidence to investigate. It does not guarantee exact replay. A hosted model may change, retrieval sources may have moved, and a refund already issued cannot be undone by replaying a trace. Preserve permitted snapshots where needed, distinguish captured outputs from fresh calls, and test tool flows against fixtures rather than repeating live actions.
Seven capabilities, with boundaries that matter
I use seven capabilities to check platform coverage. They are responsibilities to account for, not a prescription for seven new microservices. An existing gateway may cover model access and parts of policy; the current telemetry stack may already handle most observability.
| Capability | Decision it must support | Boundary to settle |
|---|---|---|
| Model access | Which models may this workload call, under which limits? | Platform manages credentials and enforcement; application owner selects models that pass its quality tests. |
| Data context | Which records may this user retrieve, and how fresh must they be? | Data owner defines access and freshness; retrieval implementation must preserve them. |
| Agent runtime | Which actions may this agent take, and when must it stop? | Tool owner defines permissions and side effects; runtime enforces step, time and usage limits. |
| Evaluation | Is this release good enough for this task? | Application owner sets acceptance criteria; platform supplies runners and release integration. |
| Serving | How do we expose, change and withdraw the endpoint? | Reuse deployment controls; version AI configuration alongside application code. |
| Observability | Can we explain behaviour and attribute spend? | Platform supplies trace plumbing; service owner responds to alerts and investigates failures. |
| Policy | Where is each restriction enforced, and who can approve an exception? | Security and data owners set requirements; enforcement belongs at the relevant call or access boundary. |
The AI Platform Operating Model gives a structured view of that scope. Three boundaries deserve particular care.
Model access should not erase model differences. A gateway can isolate keys, enforce quotas and attach cost tags. It cannot make two models interchangeable. A fallback may change tool selection, output format or answer quality. The application owner should approve fallback behaviour through evaluation, with the selected model visible in the trace. Leave provider-specific features accessible where the workload needs them.
Retrieval permissions belong to the requesting identity. A shared knowledge-base credential is convenient until it returns another customer’s records. Apply tenancy and access checks during retrieval, and include those boundaries in tests. The platform team can provide the mechanism; it cannot decide who is entitled to see the source data. Freshness is a data-owner commitment, not something a vector database supplies by itself.
Tool permission and action approval are different controls. Registering a refund tool does not authorise every refund. Its implementation still needs to enforce account scope, amount limits and any required human approval. Retries need explicit treatment: a timed-out call may have completed its side effect. Record the outcome and use idempotency controls where supported before allowing another attempt.
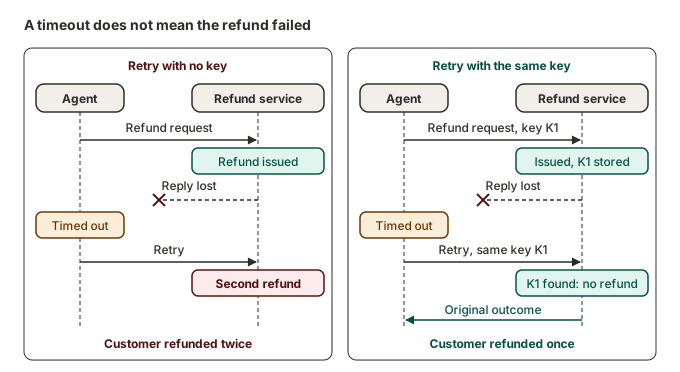
These are the places where a shared template earns its maintenance cost. A catalogue entry saying “safe agent” does not.
Share controls without transferring accountability
The platform team owns shared services: availability, supported interfaces, enforcement mechanisms and operational documentation. The application team owns the agent’s task, its quality threshold and the consequences of its actions. Data and tool owners retain authority over their resources.
For the support agent, I would assign the application owner responsibility for incorrect-answer rates and refund behaviour. The platform owner would respond if model access or trace collection failed. The data owner would handle stale policy documents. Security would approve any exception to the tool-access rules. Each needs a route into the same incident, rather than four dashboards with no agreed handoff.
Cost follows the same division. The platform meters calls and enforces agreed limits; the service owner decides whether the workload is worth its cost. A spend alert needs a recipient and an action. If nobody can suspend the agent when it exceeds its allowance, attribution is only reporting. The circuit breakers in FinOps for AI cover that distinction.
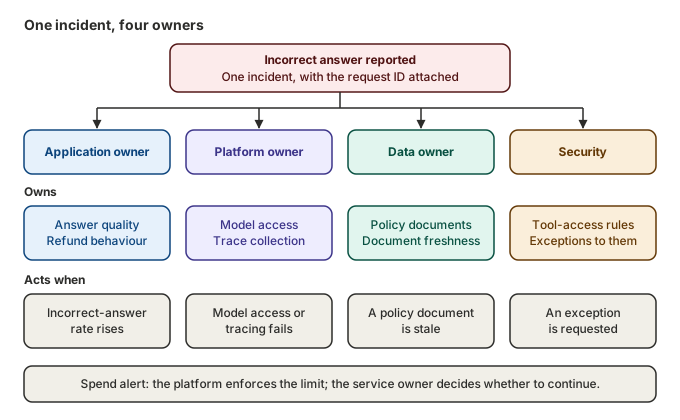
This is the product work behind an internal developer platform: supported defaults, clear customers and feedback from actual use. Measure whether another team can adopt the path and operate its workload without negotiating every boundary again.
When a separate AI team makes sense
A specialist team can be useful while demand is uncertain, while evaluation methods are being developed, or when self-hosted models require expertise the existing platform team lacks. An enablement team can help application teams discover requirements before those requirements deserve a shared service.
The decision turns on what is being shared and who can support it. One experimental workload does not necessarily justify a central agent runtime. Several teams separately building credential management, retrieval access checks and usage accounting are a stronger case for platform investment.
I would give a specialist team explicit integration obligations: use the organisation’s identity system, emit traces into incident tooling, attribute costs to service owners, and document who supports each production dependency. Revisit ownership when other teams start depending on its interfaces. A separate reporting line is manageable; an unowned production boundary is not.
Platform extension is my default where those shared services already work. It still costs engineering time and can delay teams if every model or tool change requires central approval. Keep workload-specific decisions with application owners, and centralise controls that need consistent enforcement across them.
Use 90 days to prove one supported path
A 90-day pilot is a planning boundary, not a delivery guarantee. I would attempt it with an existing deployment platform, approved model access, a usable telemetry stack, one application team and named data, security and platform owners with time allocated to the work. Procurement, residency approval or new accelerator infrastructure may require a different schedule.
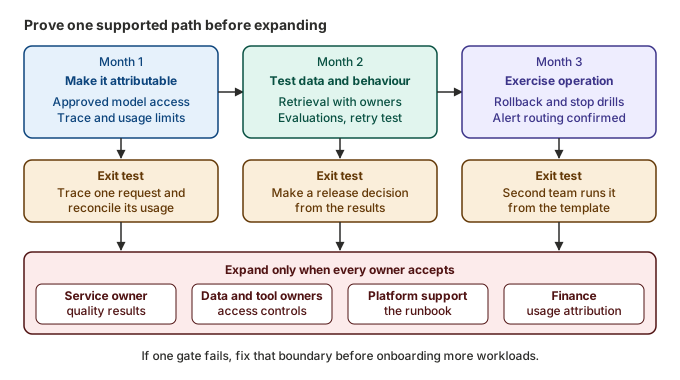
Keep the pilot to the support workflow. Start with draft responses reviewed by a person and read-only tools. Introduce refund execution only after its permissions, approval rules and failure handling pass testing. Reuse existing infrastructure wherever it meets the requirements.
First month: make the request attributable
Connect the workload to approved model access. Keep provider credentials out of application code, enforce access by service identity, and attach release, prompt, model and cost identifiers to the trace. Set usage limits and appoint the person who receives a breach alert.
The exit test is an investigation exercise: select a pilot request and identify the owning service, deployed configuration, model calls and attributable usage. Reconcile the usage record with provider reporting, documenting any estimation or delay. If that cannot be done, adding more agents will multiply the gap.
Second month: test data access and behaviour
Add the retrieval sources needed for this workflow, with their owners, access rules and freshness requirements. Build an evaluation set from permitted examples, covering correct answers, insufficient evidence, cross-customer access attempts and tool failures. Record the expected outcome and acceptance threshold for each category before judging a release.
Run those checks when prompts, models, retrieval configuration or tools change. Test authorised tool calls as well as denied ones. Inject a timeout and verify that retry handling cannot issue a duplicate refund.
The exit test is a release decision supported by results. The application owner must be able to explain which failures block deployment, which require human review and which are acceptable within the pilot’s scope.
Third month: exercise operation and adoption
Practise withdrawing a faulty release, disabling tool access and stopping a workload at its usage limit. Confirm who receives each alert and what they can do. Rollback must restore the relevant prompt and retrieval configuration as well as application code; it cannot reverse completed external actions.
Then ask a second team to use the template and documentation. Watch where it needs help. That identifies what belongs in the shared platform and what was merely knowledge held by the pilot team.
Expand only when the service owner accepts the quality results, data and tool owners accept the access controls, platform support accepts the runbook, and finance can follow the usage attribution. If one gate fails, fix that boundary before onboarding more workloads. Decision rights and exception handling belong in the AI Governance Operating Model.
The test before you expand
Return to the incorrect support answer. Can the on-call engineer identify the release, inspect the permitted retrieval evidence, follow the tool calls and stop further actions? Can the service owner explain the cost and decide whether to continue?
Those answers are the acceptance test. A catalogue and a completed 90-day plan are not enough. I would expand the platform when a second team can answer those questions using the supported path—and knows who to call when it cannot.
Source: https://bradshaw.cloud/writing/ai-platform-operating-model/